

By Abed Mohammad Kamaluddin, Director, Custom Cloud Solutions, Marvell, and Vienna Alexander, Marketing Content Professional, Marvell
For most of the last decade, scaling AI meant scaling compute. If you built faster accelerators and wired enough of them together, the models would follow.
That is no longer the whole picture. Models now run to hundreds of billions of parameters with extensive context windows, and whether an expensive accelerator is working or just waiting comes down to memory: how much you have, how fast you can reach it, and how much time you lose moving data around.
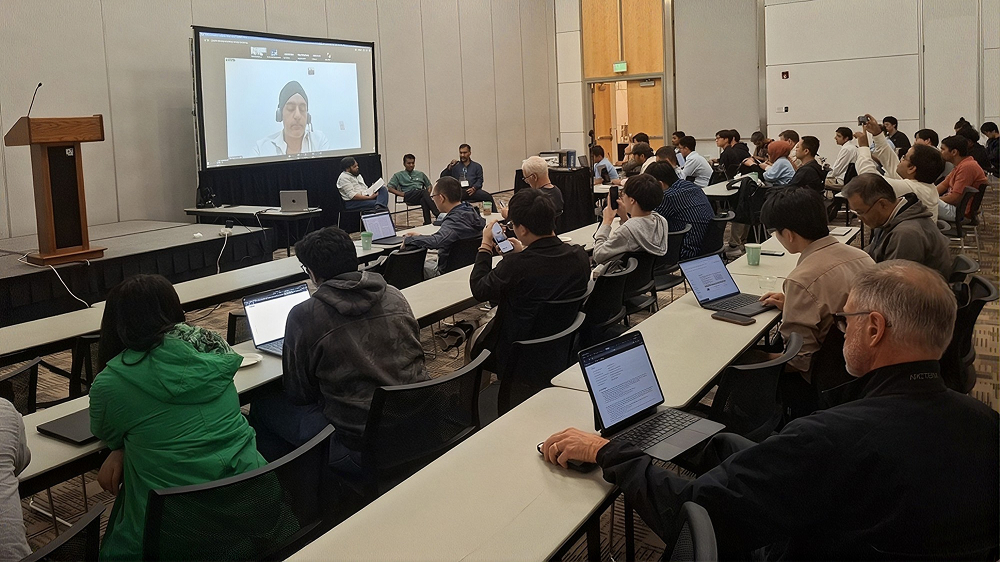
Once memory leaves the server and rides a switched fabric, is it still memory, or has it become a network? This was the central question of MemNetAI, the first workshop on Memory-Semantic Networking for AI-Scale Systems, launched by Marvell with researchers from IIT Hyderabad and IIIT Delhi. Held at ACM SIGCOMM 2026 in Denver and guided by a program committee spanning academia and industry, it brought speakers from Cornell, alongside industry experts and researchers presenting their work, to debate these questions on the bleeding edge of AI infrastructure.
By Eyal Worthalter, Director, Security Sales, Marvell
For more than a decade, the cloud has been rewriting the rules of cryptographic security. Signing, certificate management, tokenization and encryption key management have all found their way from on-premises hardware security modules (HSMs) into fully managed cloud services. But one corner of the HSM world has stubbornly resisted that shift: payments.
Until now, there has been no true cloud HSM for payments. That is changing with Azure Cloud HSM v2, a new offering built jointly by Marvell, Microsoft and Utimaco, entering public preview in September 2026.
To understand why this matters, it helps to look back at where payment security came from, and why it took a different path than the rest of the cryptography world.
Where It All Started: The Atalla Box
This is the payments chapter of a much broader evolution in Azure key management. Azure began by making HSM backed key protection available as a shared cloud service, expanded to dedicated HSM appliances for customers requiring exclusive hardware control, and then evolved toward cloud-native, single-tenant HSM services that deliver tenant isolation, customer control, and cloud-scale operations without requiring customers to manage the underlying hardware. Azure Payment HSM v2 extends that evolution to the highly specialized world of payment cryptography.
By Chander Chadha, Director of Product Marketing, Storage Products, Marvell
As AI models grow larger and inference workloads scale, larger models, longer context windows and growing KV caches are driving demands on memory resources. Traditional CPU-centric networked JBOF (Just Bunch of Flash) can’t keep pace with the throughput, latency, and efficiency requirements of these modern AI clusters.
DPU (data processing unit) -based storage is a compelling alternative to traditional storage, acting as the broker between the network and SSD for remote storage. By offloading storage, networking and security processing from the host CPU onto a dedicated DPU, AI infrastructure can move data closer to compute, reduce latency, and free up valuable CPU cycles for AI workloads.
To address this need, Marvell offers the OCTEON DPU family, purpose-built for hyperscale cloud workloads and data center applications, extending its use specifically into network storage acceleration for AI environments.
By Khurram Malik, Associate Vice President, Custom Cloud Solutions, Marvell
The rapid growth of AI is creating unprecedented demand for memory capacity. As models get larger and workloads become more data-intensive, traditional server architectures are increasingly challenged to scale memory efficiently.
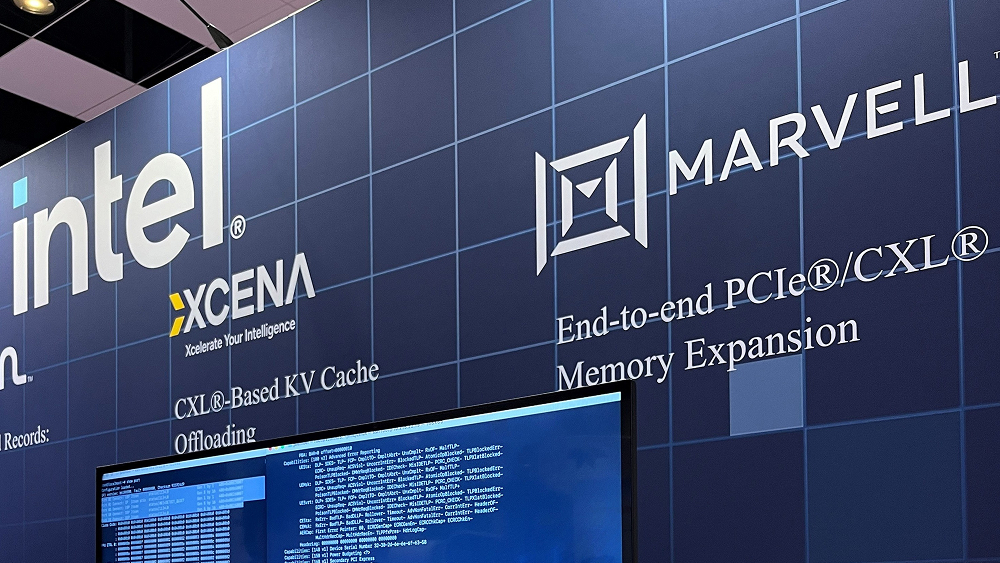
At Flash Memory Summit (FMS), Marvell demonstrated how CXL can enable a more flexible and scalable approach to memory infrastructure, showcasing an end-to-end architecture at the Intel® booth.
The demonstration combined an Intel platform with three Marvell® technologies: Structera® X CXL memory expander, Structera® S CXL switch and Alaska® P PCIe retimer. Together, they demonstrated how memory expansion, CXL switching and high-speed PCIe connectivity can work together within a real server platform.
By Arifur Rahman, Director of Product Marketing, Custom Cloud Solutions, Marvell
Memory has become the defining constraint of modern AI infrastructure. Large language models, in-memory databases, and deep learning recommendation models all share the same bottleneck: there is never enough DRAM. Compute Express Link (CXL) was designed to break that bottleneck but a CXL memory expander is only as valuable as the breadth of platforms it can run on.
That is why ecosystem enablement is a core pillar of Marvell's CXL strategy. Today we are marking a new milestone: successful interoperability of the Marvell® Structera™ X CXL memory-expansion controller with the NVIDIA Vera CPU platform.